
We're also offering an exclusive FREE vLLM POC — For the first 5 eligible companies to apply.


The open AI stack we deploy and tune
 NVIDIA Dynamo
 KServe
 Ollama
 Terraform
 GitHub Actions
 Oracle Cloud
 Azure
 Google Cloud
Why choose us?
Vendor agnostic
No strings attached
We meet you where you are
We're not resellers
Customer-centric
Trustworthy partnership
Transparency & Integrity
We learn and share together
Flexibility
Tailored services (EN/FR)
Strive for innovation
Not scared of new tech.
Security First
Protect your assets and ensure compliance with industry standards.
Private AI
We deploy LLM inference for you in the Cloud or Hybrid.
OSS friendly
We believe in Open Source's role in your innovation.
Ubiquitous
We serve you in the Cloud or On-Prem.
We listen
Your needs matter first, and we know it.
Solutions
AI Infrastructure Automation
No more click-ops. Your AI platform lives in Git and runs itself: Terraform and scripts provision it, Argo CD syncs every change, Kueue and KAI Scheduler queue GPU jobs, Run:ai shares GPUs, Karpenter scales spot and flex nodes with traffic, Anyscale runs Ray batch jobs off-peak, health checks and self-healing keep it up, lights-out schedules switch idle GPUs off at night, and benchmarks plus observability prove every change.
Multi-Cloud AI Infrastructure
One portable AI stack, every layer covered: gateway and guardrails, model serving, Kubernetes and GPUs. We run it on AWS, Azure, Google Cloud, OCI, GPU clouds like CoreWeave and Nebius, or your own data center, and place each workload where GPUs, data and budget fit best, without lock-in.
Inference Performance & Cost Optimization
Get more out of every GPU. We benchmark your models on your own traffic, then tune the four levers below so you hit latency targets at a lower cost per token.
- ThroughputMore tokens from the GPUs you already pay for.batching · quantization · parallelism
- LatencyFaster first tokens, steady under load.KV-cache reuse · prefix caching · speculative decoding
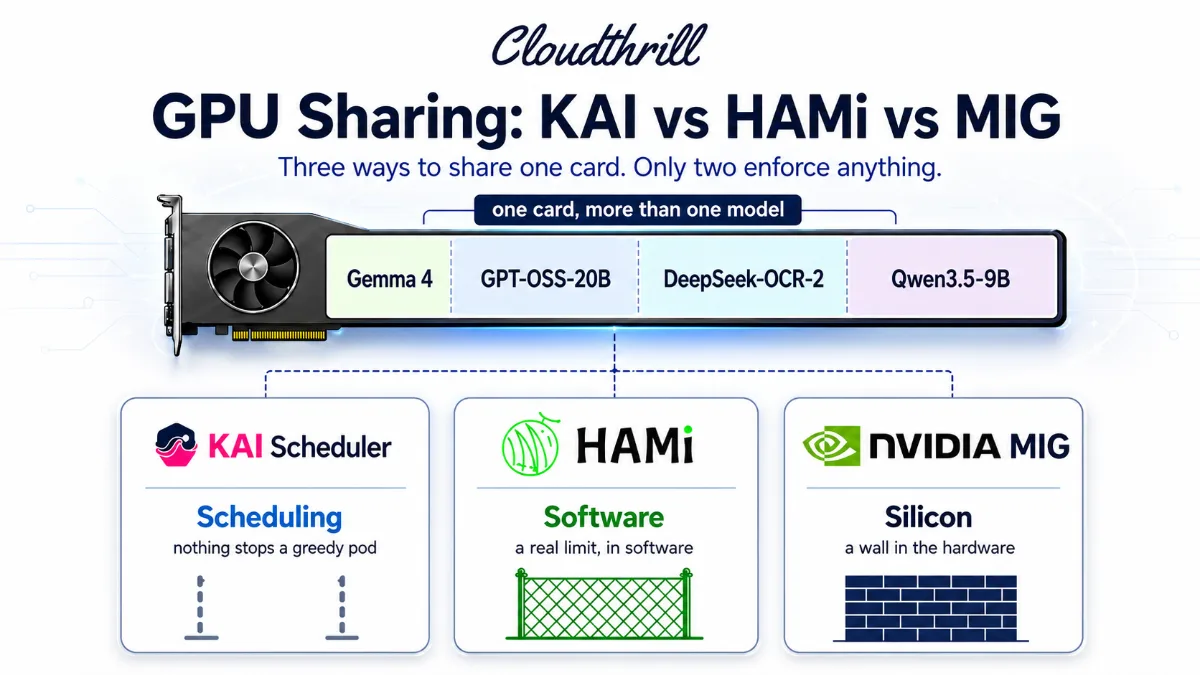
- CostFewer or cheaper GPUs for the same traffic.right-sizing · GPU sharing · precision
- ScaleAbsorb spikes without paying for idle capacity.autoscaling · KV-aware routing · P/D disaggregation
LLM Gateway, Routing & Guardrails
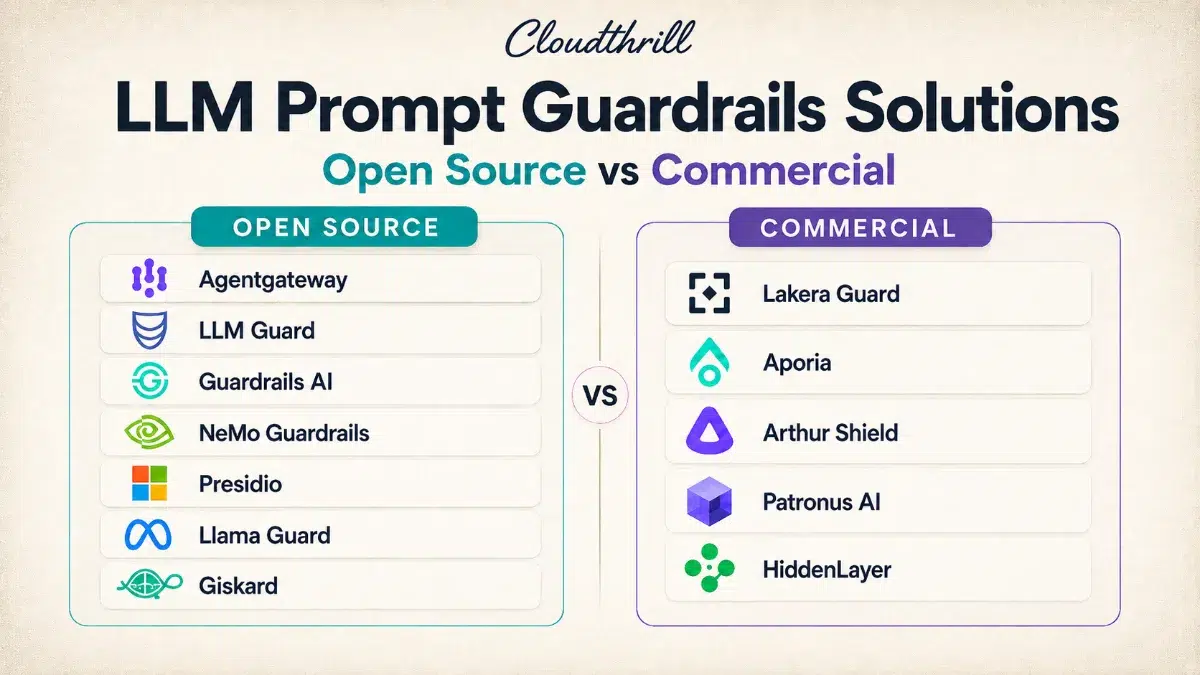
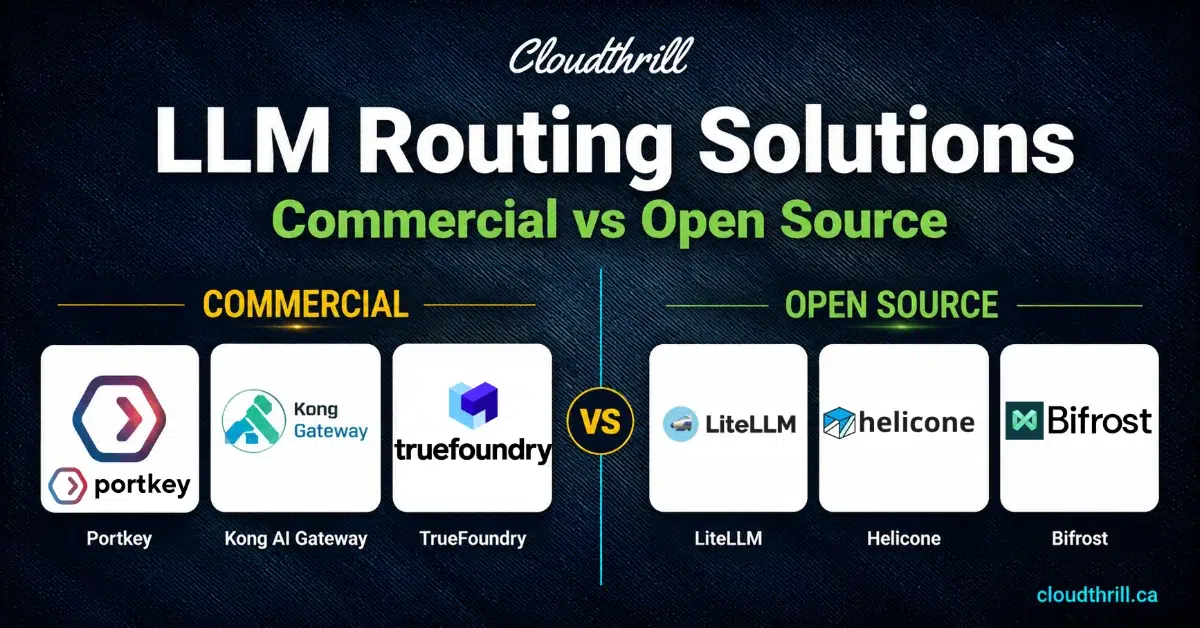
One secure front door for every model, built mostly on open source. Agentgateway blocks known attacks and masks PII at the edge with near-zero latency, LiteLLM routes each request to the right model with per-user budgets, and LLM Guard catches the subtle injections that patterns miss, so your models only ever see clean prompts.

Training & Advisory
Grow your team's skills while we build. Hands-on workshops on Kubernetes, Terraform and the open AI serving stack, architecture reviews, and AI inference proofs of concept that show what works before you invest.
How we work
Four steps, from first assessment to a team that runs it themselves.
- 01
Assess
AI infrastructure and GPU readiness review: your workloads, models, data constraints, and cloud vs. on-prem.
You getassessment, sizing & roadmap
- 02
Build
From proof of concept to production: Kubernetes, LLM serving, single sign-on and observability, all as code in your account.
You geta working platform, code handed over
- 03
Run
Ongoing optimization and management after go-live: upgrades, model roll-outs, cost and performance tuning.
You geta platform that keeps improving
- 04
Train
Corporate training and advisory on AI infrastructure, DevSecOps and GPU economics, in English or French.
You getteams that run it themselves
What we stand for?
CloudThrill is a consulting firm dedicated to providing a vendor- and platform-agnostic approach, ensuring our customers receive support no matter where their journey takes them. Whether it’s AI inference, Cloud operations, Automation, Modernisation of infrastructure estate, our mission is to make sure our clients always have the best solutions tailored to their unique needs, fueled by our quest for innovative solutions. Learn more about our values from our founder Kosseila hd

What is AI inference infrastructure?
Everything needed to serve a trained model in production: GPUs, Kubernetes, a serving engine such as vLLM, a gateway in front, plus monitoring and security. We build and run that layer for you, in your cloud or data center.
Why run private inference instead of calling a public API?
Your prompts and data stay inside your own account, costs stay predictable as volume grows, and you choose the models. For many teams it also makes compliance simpler.
Which models and workloads can you deploy?
Practically any model on Hugging Face, plus your own fine-tuned or private models, as long as they run on vLLM, SGLang or the Transformers backend. That ranges from small models that fit on one GPU to recent flagship open-weight models such as DeepSeek, Kimi, MiniMax and GLM, along with embedding and reranking models and the RAG or agent backends that use them, on NVIDIA or AMD GPUs.
Which clouds and GPU providers do you work with?
AWS, Azure, Google Cloud and OCI, GPU clouds such as CoreWeave, Nebius and Civo, and on-prem Kubernetes. Everything is written in Terraform, so it moves with you.
How do we go from prototype to production?
Start with a proof of concept on your own data and measure quality, latency and cost. Then harden it: autoscaling, gateway, guardrails, observability and a runbook your team owns. Apply for the free vLLM PoC.
How can we reduce the cost of inference at scale?
Right-size the GPUs, raise utilization with batching, caching and GPU sharing, route simple requests to smaller models, and scale down outside peak hours. Those basics get you started; the bigger savings come from tuning your own stack on your own traffic: engine settings, KV-cache offloading, quantization and disaggregated serving. Talk to us about an inference optimization engagement.
Do you offer training or ongoing support?
Yes. Hands-on workshops for your engineers in English or French, and ongoing support after go-live for upgrades, model roll-outs and tuning.